The Multi-Node Mirage: Quantifying Distributed Training Overhead Before Committing to the Architecture
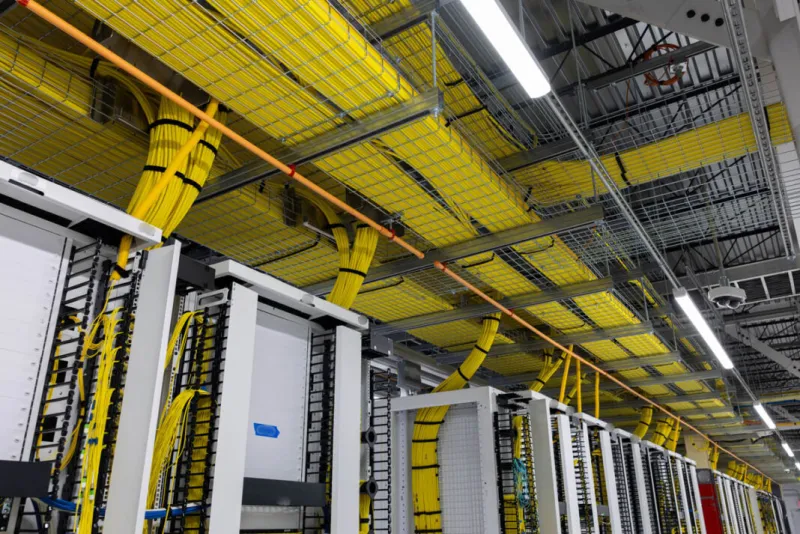
Photo: GPU server cluster data center network cables infrastructure, via www.servethehome.com
The conventional wisdom in large-scale model training has converged on a seductive simplicity: when a model outgrows a single node, distribute it across multiple nodes. The logic appears self-evident. More GPUs should mean faster training. More nodes should mean more GPUs. The arithmetic seems to close.
It frequently does not. The gap between theoretical throughput and realized throughput in distributed training environments is one of the most consistently underestimated costs in applied ML infrastructure. Understanding why—and how to measure it before committing to an architecture—is essential for any team operating at a scale where training economics materially affect project viability.
Where the Computation Budget Actually Goes
In an ideal distributed training scenario, scaling from one node to eight would yield an eightfold reduction in training time. In practice, the relationship between node count and throughput is sublinear, often dramatically so. The culprit is communication overhead: the time GPUs spend synchronizing gradients, transferring activations, or waiting for remote parameters rather than performing forward and backward passes.
The magnitude of this overhead depends on several interacting variables: the communication backend in use, the interconnect topology between nodes, the ratio of parameter count to batch size, and the specific parallelism strategy employed. None of these variables are constant across architectures, and none of them appear in the benchmark figures that typically inform infrastructure decisions.
A useful first-order characterization separates distributed training overhead into three categories.
Synchronization latency is the time spent waiting for all participating nodes to complete their local computation before a gradient update can proceed. In synchronous data-parallel training, a single slow node—whether due to hardware variance, thermal throttling, or workload imbalance—imposes its latency on the entire cluster. This effect, sometimes called the straggler problem, is well-documented but routinely underweighted in capacity planning.
Bandwidth saturation occurs when the volume of data that must be transferred between nodes during each training step exceeds the available network bandwidth. For large models with billions of parameters, all-reduce operations during gradient synchronization can generate hundreds of gigabytes of traffic per step. Ethernet-connected clusters are particularly vulnerable; even NVLink-equipped nodes can encounter saturation under dense communication patterns.
Protocol overhead encompasses the fixed costs of collective communication operations independent of data volume—connection establishment, buffer management, and scheduling latency. These costs are small per operation but accumulate significantly across training runs measured in tens of thousands of steps.
Measuring Overhead Before You Scale
The most reliable approach to quantifying distributed training overhead is profiling, not estimation. Modern training frameworks provide instrumentation sufficient to decompose wall-clock training time into computation and communication components. PyTorch's profiler, for instance, can attribute GPU time to specific operations with enough granularity to identify whether a cluster is compute-bound or communication-bound.
The key metric to establish is the communication-to-computation ratio (CCR): the fraction of total training time consumed by inter-node data transfer versus actual tensor operations. A CCR below 0.15 generally indicates that the distributed strategy is well-matched to the hardware topology. A CCR above 0.30 is a strong signal that the architecture is being taxed by communication in ways that undermine the scaling rationale.
Teams should measure CCR at multiple batch sizes before committing to a distributed strategy. Communication volume in data-parallel training scales with parameter count, not batch size, meaning that larger batches amortize communication overhead across more samples per synchronization event. If your target batch size produces a high CCR, increasing batch size—where the training dynamics permit—is often more economical than adding nodes.
When Single-Node Optimization Wins
The distributed training default deserves to be challenged more often than it is. Single-node training on modern high-memory GPU configurations—A100 80GB, H100, or multi-GPU servers with NVLink—has expanded the viable model size range substantially. Many workloads that teams reflexively distribute can be accommodated on a single node with appropriate memory optimization techniques.
Gradient checkpointing, mixed-precision training, and activation recomputation collectively reduce the memory footprint of large models without proportional throughput penalties. A model that requires 160GB of GPU memory in its naive form may fit within a single 8xA100 node after applying these techniques—eliminating inter-node communication entirely and realizing the full theoretical throughput of the hardware.
The economic case for single-node optimization is particularly strong for teams operating on cloud infrastructure, where inter-node bandwidth is a provisioned resource that carries real cost. A training job that runs 40% faster on a single high-memory node than on a multi-node cluster with communication overhead is also a training job that costs less per experiment and is easier to debug when something goes wrong.
Evaluating Parallelism Strategies Quantitatively
When distributed training is genuinely necessary—either because model size exceeds single-node capacity or because throughput requirements mandate it—the choice of parallelism strategy has a first-order impact on communication overhead.
Data parallelism, the most common approach, replicates the full model on each node and synchronizes gradients after each backward pass. Its communication cost scales with parameter count and is largely independent of model architecture, making it predictable but potentially expensive for large models.
Tensor parallelism partitions individual layers across devices, reducing per-device memory requirements but introducing communication at every layer boundary. The overhead is highly sensitive to the arithmetic intensity of the model—transformer attention layers, with their large matrix operations, tolerate tensor parallelism reasonably well; smaller models with lower arithmetic intensity do not.
Pipeline parallelism assigns different layers to different devices, communicating activations between stages rather than gradients across all nodes. It can achieve high hardware utilization when pipeline stages are balanced, but introduces pipeline bubbles—idle periods while earlier stages complete—that reduce effective throughput.
The economically optimal strategy for a given workload is rarely one of these approaches in isolation. Hybrid configurations—tensor parallelism within a node, data parallelism across nodes—can exploit high-bandwidth intra-node interconnects for communication-intensive operations while limiting the volume of traffic crossing slower inter-node links.
The Breakeven Calculation
The decision to move from single-node to multi-node training should be grounded in a concrete breakeven analysis that accounts for communication overhead, not just raw hardware capacity.
The relevant comparison is not theoretical FLOPS across configurations. It is effective samples per second per dollar—actual training throughput, measured under realistic communication conditions, divided by the fully-loaded infrastructure cost of each configuration. Teams that perform this calculation before committing to distributed infrastructure consistently find that the breakeven point arrives later than intuition suggests.
Distributed training at scale is a legitimate and often necessary engineering capability. But it is not a free scaling lever. Treating it as one is how training budgets get consumed by network switches rather than model improvements.